⚽ Soccer with sportsdataverse-py
This page is the executed notebook
13_soccer_intro.ipynb: download it to run it yourself.
From the Premier League to the World Cup, sportsdataverse.soccer gives you the global
game in tidy polars DataFrames — no API key, no config, just pip and import.
The entire surface is built on ESPN's public Site v2, Web v3, and Core v2 endpoints and
surfaced through a single family of espn_soccer_* wrappers that accept a league= slug
— so one call covers Premier League, MLS, Champions League, La Liga, or any of the other
leagues ESPN tracks. Twelve league aliases (espn_epl_*, espn_mls_*, espn_ucl_*, …) let
you drop the league= argument entirely when you only ever work one competition.
R user? The closest companion for the European game is worldfootballR. For women's basketball orbiting the same ESPN platform, see wehoop.
Let's kick it off! ⚽
🧰 The toolbox
Everything returns a tidy polars DataFrame by default — pass
return_as_pandas=True for pandas. The wrappers return the raw ESPN JSON by
default; pass `` to run the built-in parser. ⭐ marks the
most commonly used entry points.
Core wrappers (pass league= slug)
| Function | What it gives you |
|---|---|
espn_soccer_scoreboard | ⭐ Match results / live scores for a date |
espn_soccer_standings | ⭐ League / conference / group standings |
espn_soccer_summary | ⭐ Full match summary — lineups, key events, team stats, commentary |
espn_soccer_teams_site | ⭐ Every team in the league (grab team_ids) |
espn_soccer_team_roster | One team's current squad |
espn_soccer_team_schedule | A team's fixtures & results |
espn_soccer_news | Latest news headlines for a league |
espn_soccer_injuries | Current injury list |
espn_soccer_player_info | Player bio & metadata |
espn_soccer_player_stats | Player season statistics |
espn_soccer_game_probabilities | In-game win probabilities |
Parsers (turn raw JSON into polars)
| Parser | Paired with |
|---|---|
parse_soccer_scoreboard | espn_soccer_scoreboard |
parse_soccer_standings | espn_soccer_standings |
parse_soccer_summary | espn_soccer_summary — 11-section dispatcher |
parse_soccer_teams | espn_soccer_teams_site |
parse_soccer_team_roster | espn_soccer_team_roster |
League slugs quick reference
league= | Competition |
|---|---|
eng.1 | Premier League |
usa.1 | MLS |
uefa.champions | Champions League |
esp.1 | La Liga |
ger.1 | Bundesliga |
ita.1 | Serie A |
fra.1 | Ligue 1 |
uefa.europa | Europa League |
usa.nwsl | NWSL |
mex.1 | Liga MX |
fifa.world | FIFA World Cup |
fifa.wwc | FIFA Women's World Cup |
🔌 Setup
pip install --pre sportsdataverse
pip install --pre "sportsdataverse[soccer,sdvplot,sportypy]"   # optional: event data + the shot map
No API key required. All calls go to ESPN's public endpoints.
import polars as pl
import sportsdataverse.soccer as soccer
from sportsdataverse.soccer.soccer_espn_parsers import (
    parse_soccer_scoreboard,
    parse_soccer_standings,
    parse_soccer_summary,
    parse_soccer_teams,
    parse_soccer_team_roster,
)

# The league aliases live in sub-modules;
# import them for the alias-demo section later.
from sportsdataverse.soccer import epl, mls, ucl, laliga, bundesliga

print('polars version:', pl.__version__)
polars version: 2.0.0
ESPN's live endpoints are seasonal and occasionally rate-limited, so a tiny
safe() helper runs them defensively — you get the frame when the feed is up,
and a friendly one-liner when it isn't (never a scary traceback). 🛟
from sportsdataverse.errors import AssetFetchError, NoDataError

def safe(label, thunk):
    try:
        out = thunk()
        print(f'✅ {label}')
        return out
    except (NoDataError, AssetFetchError) as e:
        print(f"\u23ed\ufe0f  {label}: {type(e).__name__}: {e}")
        return None
📅 Scoreboard — a day's results
espn_soccer_scoreboard
returns every match for a league on a given date. Pass dates=YYYYMMDD; omit
it to get today's slate. The raw payload is a nested ESPN JSON dict — pass
`` to flatten it into a tidy polars frame, or call
parse_soccer_scoreboard explicitly on the raw dict.
We'll start with a Premier League match-day.
# Raw payload (the default) — useful when you need the full nested structure.
raw_board = safe(
    'EPL scoreboard (raw)',
    lambda: soccer.espn_soccer_scoreboard(league='eng.1', dates=20240310),
)
type(raw_board), list(raw_board.keys()) if isinstance(raw_board, dict) else 'unavailable'
✅ EPL scoreboard (raw)


(polars.dataframe.frame.DataFrame, 'unavailable')
# Parsed frame — one row per match.
board = safe(
    'EPL scoreboard (parsed)',
    lambda: parse_soccer_scoreboard(
        soccer.espn_soccer_scoreboard(league='eng.1', dates=20240310)
    ),
)
if board is not None and getattr(board, 'height', 0):
    keep = [c for c in board.columns
            if c in ('game_id', 'name', 'short_name', 'status_type_description',
                     'home_team_abbreviation', 'away_team_abbreviation',
                     'home_score', 'away_score', 'date')]
    out = board.select(keep).head()
else:
    out = 'no scoreboard data for that date'
out
✅ EPL scoreboard (parsed)


'no scoreboard data for that date'
print('board shape:', getattr(board, 'shape', 'N/A'))
print('columns:', getattr(board, 'columns', []))
board shape: (0, 0)
columns: []
🏆 Standings
espn_soccer_standings
flattens the league table into one row per team per group/conference. The
group column is what makes this multi-competition friendly:
- Single-table leagues (EPL, La Liga, Bundesliga): one group, one table.
- Conference leagues (MLS — Eastern/Western Conferences): filter on
groupto isolate a conference. - Group-stage tournaments (Champions League, World Cup): each
group/group-stage pod gets its own
grouplabel.
We'll pull the Premier League table and an MLS table side by side.
epl_table = safe(
    'EPL standings',
    lambda: parse_soccer_standings(
        soccer.espn_soccer_standings(league='eng.1', season=2023)
    ),
)
if epl_table is not None and getattr(epl_table, 'height', 0):
    keep = [c for c in epl_table.columns
            if c in ('rank', 'team_name', 'games_played', 'wins', 'losses',
                     'draws', 'goals_for', 'goals_against', 'goal_difference',
                     'points', 'group')]
    out = epl_table.select(keep).head(10)
else:
    out = 'standings unavailable right now'
out
✅ EPL standings


'standings unavailable right now'
# MLS standings — multiple groups (Eastern/Western Conference)
mls_table = safe(
    'MLS standings',
    lambda: parse_soccer_standings(
        soccer.espn_soccer_standings(league='usa.1', season=2023)
    ),
)
if mls_table is not None and getattr(mls_table, 'height', 0):
    keep = [c for c in mls_table.columns
            if c in ('rank', 'team_name', 'wins', 'losses', 'draws', 'points', 'group')]
    print('MLS groups:', mls_table['group'].unique().to_list() if 'group' in mls_table.columns else 'n/a')
    out = mls_table.select(keep).head(10)
else:
    out = 'MLS standings unavailable right now'
out
✅ MLS standings


'MLS standings unavailable right now'
🎬 Match summary — the 11-section dispatcher
espn_soccer_summary fetches
the full ESPN Site v2 summary payload for a single match (~500 KB–1 MB of
nested JSON). parse_soccer_summary turns that into a dict of polars
DataFrames, one key per section:
| Section | Content |
|---|---|
header | Match header — teams, score, status, venue |
lineups | Starting XI + substitutes, one row per player |
key_events | Goals, cards, own goals, substitutions |
team_stats | Per-team aggregate stats (shots, possession, passes …) |
commentary | Live commentary log, one row per broadcast call |
leaders | Statistical leaders (top scorers, etc.) |
standings | In-payload mini standings snapshot |
head_to_head | H2H history between the two clubs |
last_five | Each team's most recent 5 results |
game_info | Venue, attendance, referee, season details |
shootout | Penalty shootout rows (when applicable) |
We'll use a Chelsea vs. Manchester City EPL match
(event 656009 — 12 Nov 2023) to walk through each section.
EVENT_ID = 656009  # Chelsea vs Man City, EPL, 12 Nov 2023

raw_summary = safe(
    f'EPL summary event {EVENT_ID}',
    lambda: soccer.espn_soccer_summary(league='eng.1', event_id=EVENT_ID),
)
# Parse all 11 sections at once
if raw_summary is not None:
    frames = parse_soccer_summary(raw_summary)
    print('sections parsed:', list(frames.keys()))
    print('rows per section:', {k: v.height for k, v in frames.items()})
else:
    frames = {}
✅ EPL summary event 656009
sections parsed: ['header', 'lineups', 'key_events', 'team_stats', 'commentary', 'leaders', 'standings', 'head_to_head', 'last_five', 'game_info', 'shootout']
rows per section: {'header': 0, 'lineups': 0, 'key_events': 0, 'team_stats': 0, 'commentary': 0, 'leaders': 0, 'standings': 0, 'head_to_head': 0, 'last_five': 0, 'game_info': 0, 'shootout': 0}
Section: header — match overview
header = frames.get('header')
if header is not None and header.height:
    keep = [c for c in header.columns
            if c in ('name', 'home_team_name', 'away_team_name',
                     'home_score', 'away_score', 'status_type_description',
                     'venue_full_name', 'date')]
    out = header.select(keep)
else:
    out = 'header section unavailable'
out
'header section unavailable'
Section: lineups — starting XIs and substitutes
lineups = frames.get('lineups')
if lineups is not None and lineups.height:
    keep = [c for c in lineups.columns
            if c in ('team_name', 'athlete_display_name', 'position_name',
                     'jersey', 'starter', 'subbedIn', 'subbedOut')]
    out = lineups.select(keep).head(10)
else:
    out = 'lineups section unavailable'
out
'lineups section unavailable'
Section: key_events — goals, cards, substitutions
key_events = frames.get('key_events')
if key_events is not None and key_events.height:
    keep = [c for c in key_events.columns
            if c in ('clock_display_value', 'team_name', 'athlete_display_name',
                     'type_text', 'text', 'score_value')]
    out = key_events.select(keep).head()
else:
    out = 'key_events section unavailable'
out
'key_events section unavailable'
Section: team_stats — possession, shots, passes …
team_stats = frames.get('team_stats')
if team_stats is not None and team_stats.height:
    print('team_stats columns:', team_stats.columns)
    out = team_stats.head()
else:
    out = 'team_stats section unavailable'
out
'team_stats section unavailable'
Section: commentary — live match log
commentary = frames.get('commentary')
if commentary is not None and commentary.height:
    keep = [c for c in commentary.columns
            if c in ('clock_display_value', 'type_id', 'text')]
    out = commentary.select(keep).head(6)
else:
    out = 'commentary section unavailable'
out
'commentary section unavailable'
Remaining sections at a glance
The remaining five sections follow the same pattern — each is a tidy
DataFrame keyed off frames["<section>"].
# Quick peek at game_info, head_to_head, last_five, leaders, shootout
for section in ('game_info', 'head_to_head', 'last_five', 'leaders', 'shootout'):
    df = frames.get(section)
    if df is not None:
        print(f'{section:20s}  shape={df.shape}  cols={df.columns[:5]}')
    else:
        print(f'{section:20s}  not in parsed frames')
game_info             shape=(0, 0)  cols=[]
head_to_head          shape=(0, 0)  cols=[]
last_five             shape=(0, 0)  cols=[]
leaders               shape=(0, 0)  cols=[]
shootout              shape=(0, 0)  cols=[]
Requesting a single section
Pass section="<name>" to parse_soccer_summary when you only need one
slice — the parser skips the rest and returns a single DataFrame directly.
if raw_summary is not None:
    ke = parse_soccer_summary(raw_summary, section='key_events')
    print(type(ke).__name__, ke.shape)
    out = ke.head(3)
else:
    out = 'summary unavailable'
out
DataFrame (0, 0)


shape: (0, 0)
┌┐
╞╡
└┘
🏟️ Teams — the master lookup
espn_soccer_teams_site
lists every team in a league. The team_id column is the key you feed into
every team-scoped call (roster, schedule, injuries …).
epl_teams = safe(
    'EPL teams',
    lambda: parse_soccer_teams(
        soccer.espn_soccer_teams_site(league='eng.1')
    ),
)
if epl_teams is not None and epl_teams.height:
    keep = [c for c in epl_teams.columns
            if c in ('team_id', 'display_name', 'abbreviation',
                     'location', 'name', 'short_display_name', 'is_active')]
    out = epl_teams.select(keep).head(10)
else:
    out = 'teams unavailable right now'
out
✅ EPL teams


'teams unavailable right now'
👥 Team roster
espn_soccer_team_roster
pulls the current squad for a single team. Pass team_id= from the teams
frame above. We'll use Arsenal (team_id=359).
ARSENAL_ID = 359  # Arsenal FC

roster = safe(
    f'Arsenal roster (team_id={ARSENAL_ID})',
    lambda: parse_soccer_team_roster(
        soccer.espn_soccer_team_roster(league='eng.1', team_id=ARSENAL_ID)
    ),
)
if roster is not None and getattr(roster, 'height', 0):
    keep = [c for c in roster.columns
            if c in ('athlete_id', 'display_name', 'jersey',
                     'position_name', 'age', 'birth_country')]
    out = roster.select(keep).head(10)
else:
    out = 'roster unavailable right now'
out
✅ Arsenal roster (team_id=359)


'roster unavailable right now'
📆 Team schedule
espn_soccer_team_schedule
returns the fixtures and results for a team in a given season. Pass season=
as an integer year to scope to a specific campaign.
team_sched = safe(
    f'Arsenal schedule 2023/24',
    lambda: soccer.espn_soccer_team_schedule(
        league='eng.1', team_id=ARSENAL_ID, season=2024,
    ),
)
if isinstance(team_sched, dict):
    # Raw payload — show top-level keys as an orientation
    print('payload keys:', list(team_sched.keys()))
elif team_sched is not None:
    print('shape:', team_sched.shape)
    print(team_sched.head())
else:
    print('schedule unavailable right now')
✅ Arsenal schedule 2023/24
shape: (38, 21)
shape: (5, 21)
┌────────┬────────────┬────────────┬───────────┬───┬───────────┬───────────┬───────────┬───────────┐
│ id     ┆ date       ┆ name       ┆ short_nam ┆ … ┆ league_sh ┆ league_mi ┆ league_sl ┆ league_is │
│ ---    ┆ ---        ┆ ---        ┆ e         ┆   ┆ ort_name  ┆ dsize_nam ┆ ug        ┆ _tourname │
│ i64    ┆ str        ┆ str        ┆ ---       ┆   ┆ ---       ┆ e         ┆ ---       ┆ nt        │
│        ┆            ┆            ┆ str       ┆   ┆ str       ┆ ---       ┆ str       ┆ ---       │
│        ┆            ┆            ┆           ┆   ┆           ┆ str       ┆           ┆ bool      │
╞════════╪════════════╪════════════╪═══════════╪═══╪═══════════╪═══════════╪═══════════╪═══════════╡
│ 704656 ┆ 2025-05-25 ┆ Arsenal at ┆ ARS @ SOU ┆ … ┆ Premier   ┆ ENG.1     ┆ eng.1     ┆ false     │
│        ┆ T15:00Z    ┆ Southampto ┆           ┆   ┆ League    ┆           ┆           ┆           │
│        ┆            ┆ n          ┆           ┆   ┆           ┆           ┆           ┆           │
│ 704639 ┆ 2025-05-18 ┆ Newcastle  ┆ NEW @ ARS ┆ … ┆ Premier   ┆ ENG.1     ┆ eng.1     ┆ false     │
│        ┆ T15:30Z    ┆ United at  ┆           ┆   ┆ League    ┆           ┆           ┆           │
│        ┆            ┆ Arsenal    ┆           ┆   ┆           ┆           ┆           ┆           │
│ 704632 ┆ 2025-05-11 ┆ Arsenal at ┆ ARS @ LIV ┆ … ┆ Premier   ┆ ENG.1     ┆ eng.1     ┆ false     │
│        ┆ T15:30Z    ┆ Liverpool  ┆           ┆   ┆ League    ┆           ┆           ┆           │
│ 704619 ┆ 2025-05-03 ┆ AFC Bourne ┆ BOU @ ARS ┆ … ┆ Premier   ┆ ENG.1     ┆ eng.1     ┆ false     │
│        ┆ T16:30Z    ┆ mouth at   ┆           ┆   ┆ League    ┆           ┆           ┆           │
│        ┆            ┆ Arsenal    ┆           ┆   ┆           ┆           ┆           ┆           │
│ 704618 ┆ 2025-04-23 ┆ Crystal    ┆ CRY @ ARS ┆ … ┆ Premier   ┆ ENG.1     ┆ eng.1     ┆ false     │
│        ┆ T19:00Z    ┆ Palace at  ┆           ┆   ┆ League    ┆           ┆           ┆           │
│        ┆            ┆ Arsenal    ┆           ┆   ┆           ┆           ┆           ┆           │
└────────┴────────────┴────────────┴───────────┴───┴───────────┴───────────┴───────────┴───────────┘
🗞️ News & injuries
Two lightweight feeds round out the live suite:
espn_soccer_news— latest editorial headlines for a league, optionally limited bylimit=.espn_soccer_injuries— current injury list for a league (all teams).
news = safe(
    'EPL news',
    lambda: soccer.espn_soccer_news(league='eng.1', limit=10),
)
if isinstance(news, dict):
    articles = news.get('articles', [])
    for a in articles[:3]:
        if isinstance(a, dict):
            print('•', a.get('headline', a.get('title', str(a)))[:100])
else:
    print('news unavailable right now')
✅ EPL news
news unavailable right now
injuries = safe(
    'EPL injuries',
    lambda: soccer.espn_soccer_injuries(league='eng.1'),
)
if isinstance(injuries, dict):
    print('injury payload keys:', list(injuries.keys()))
elif injuries is not None:
    print('shape:', injuries.shape)
else:
    print('injuries feed unavailable right now')
✅ EPL injuries
shape: (0, 3)
🔗 League aliases — drop the league= argument
When you only work with one competition, the twelve league sub-modules
(epl, mls, ucl, laliga, bundesliga, seriea, ligue1, uel,
nwsl, ligamx, wc, wwc) provide pre-bound aliases where league= is
already wired in. Every espn_soccer_* function has a corresponding
espn_<alias>_* variant.
# These three calls are exactly equivalent:
soccer.espn_soccer_scoreboard(league='eng.1', dates=20240310)
epl.espn_epl_scoreboard(dates=20240310)
from sportsdataverse.soccer.epl import espn_epl_scoreboard
espn_epl_scoreboard(dates=20240310)
Here's a quick tour of three aliases side by side.
# --- EPL alias ---
epl_board = safe(
    'epl.espn_epl_scoreboard',
    lambda: parse_soccer_scoreboard(
        epl.espn_epl_scoreboard(dates=20240310)
    ),
)
if epl_board is not None and getattr(epl_board, 'height', 0):
    keep = [c for c in epl_board.columns
            if c in ('short_name', 'home_score', 'away_score', 'status_type_description')]
    out = epl_board.select(keep).head()
else:
    out = 'EPL alias unavailable'
out
✅ epl.espn_epl_scoreboard


'EPL alias unavailable'
# --- MLS alias: standings ---
mls_alias_table = safe(
    'mls.espn_mls_standings',
    lambda: parse_soccer_standings(
        mls.espn_mls_standings(season=2023)
    ),
)
if mls_alias_table is not None and getattr(mls_alias_table, 'height', 0):
    keep = [c for c in mls_alias_table.columns
            if c in ('rank', 'team_name', 'wins', 'losses', 'draws', 'points', 'group')]
    out = mls_alias_table.select(keep).head(8)
else:
    out = 'MLS alias unavailable'
out
✅ mls.espn_mls_standings


'MLS alias unavailable'
# --- UCL alias: standings (shows group labels A–H during the group stage) ---
ucl_table = safe(
    'ucl.espn_ucl_standings',
    lambda: parse_soccer_standings(
        ucl.espn_ucl_standings(season=2024)
    ),
)
if ucl_table is not None and getattr(ucl_table, 'height', 0):
    keep = [c for c in ucl_table.columns
            if c in ('rank', 'team_name', 'wins', 'draws', 'losses', 'points', 'group')]
    print('UCL groups:', ucl_table['group'].unique().sort().to_list() if 'group' in ucl_table.columns else 'n/a')
    out = ucl_table.select(keep).head(10)
else:
    out = 'UCL alias unavailable'
out
✅ ucl.espn_ucl_standings


'UCL alias unavailable'
🍳 Cookbook: common soccer tasks
The real fun is in the questions. Six recipes built from the frames we've already pulled — every one ends in a tidy, ready-to-read frame.
Recipe 1 — Derive goal difference from the standings table 📈
The standings frame already ships goals_for and goals_against;
sort by goal difference to see who dominated the scoring charts.
if (epl_table is not None and getattr(epl_table, 'height', 0)
        and {'goals_for', 'goals_against'}.issubset(epl_table.columns)):
    out = (
        epl_table
        .with_columns(
            (pl.col('goals_for') - pl.col('goals_against')).alias('gd')
        )
        .select(['rank', 'team_name', 'goals_for', 'goals_against', 'gd', 'points'])
        .sort('gd', descending=True)
        .head(10)
    )
else:
    out = 'run the standings cell above first'
out
'run the standings cell above first'
Recipe 2 — Starter vs. substitute counts from a lineup 🧮
Count the starters and bench players per team from the lineups
section of the match summary we already fetched.
lineup_df = frames.get('lineups')
if (lineup_df is not None and lineup_df.height
        and {'team_name', 'starter'}.issubset(lineup_df.columns)):
    out = (
        lineup_df
        .group_by(['team_name', 'starter'])
        .agg(pl.len().alias('players'))
        .sort(['team_name', 'starter'])
    )
else:
    out = 'run the match-summary cells above first'
out
'run the match-summary cells above first'
Recipe 3 — Goals, cards, and substitutions in the key-events log 🎯
The key_events section has a type_text column. Group it to get a
breakdown of event types for the match.
ke_df = frames.get('key_events')
if ke_df is not None and ke_df.height and 'type_text' in ke_df.columns:
    out = (
        ke_df
        .group_by('type_text')
        .agg(pl.len().alias('count'))
        .sort('count', descending=True)
    )
else:
    out = 'run the match-summary cells above first'
out
'run the match-summary cells above first'
Recipe 4 — Position breakdown of a squad 🏃
Use the parsed roster to count players by position — a quick depth-chart picture for squad assessment.
if (roster is not None and getattr(roster, 'height', 0)
        and 'position_name' in roster.columns):
    out = (
        roster
        .group_by('position_name')
        .agg(pl.len().alias('players'))
        .sort('players', descending=True)
    )
else:
    out = 'run the team-roster cell above first'
out
'run the team-roster cell above first'
Recipe 5 — Multi-league standings in one loop 🌍
Because the league slug is just a string, looping over several competitions is trivial. Count the teams in the standings table for four top leagues.
leagues = {
    'eng.1': 'Premier League',
    'esp.1': 'La Liga',
    'ger.1': 'Bundesliga',
    'ita.1': 'Serie A',
}
rows = []
for slug, name in leagues.items():
    result = safe(
        f'{name} standings',
        lambda s=slug: parse_soccer_standings(
            soccer.espn_soccer_standings(league=s, season=2023)
        ),
    )
    rows.append({
        'league': name,
        'slug': slug,
        'teams': result.height if result is not None else 0,
        'groups': (result['group'].n_unique() if 'group' in result.columns else 1)
                  if result is not None and result.height else 0,
    })

pl.DataFrame(rows)
✅ Premier League standings


✅ La Liga standings


✅ Bundesliga standings


✅ Serie A standings


shape: (4, 4)
┌────────────────┬───────┬───────┬────────┐
│ league         ┆ slug  ┆ teams ┆ groups │
│ ---            ┆ ---   ┆ ---   ┆ ---    │
│ str            ┆ str   ┆ i64   ┆ i64    │
╞════════════════╪═══════╪═══════╪════════╡
│ Premier League ┆ eng.1 ┆ 0     ┆ 0      │
│ La Liga        ┆ esp.1 ┆ 0     ┆ 0      │
│ Bundesliga     ┆ ger.1 ┆ 0     ┆ 0      │
│ Serie A        ┆ ita.1 ┆ 0     ┆ 0      │
└────────────────┴───────┴───────┴────────┘
Recipe 6 — Pandas interop 🐼
Every parser accepts return_as_pandas=True, and any polars frame
converts with .to_pandas(). Once you're in pandas land the full
pandas / NumPy / scikit-learn world opens up.
if epl_table is not None and getattr(epl_table, 'height', 0):
    epl_pd = epl_table.to_pandas()
    print(type(epl_pd).__name__, '|', epl_pd.shape)
    numeric = [c for c in ('wins', 'losses', 'draws', 'goals_for', 'goals_against', 'points')
               if c in epl_pd.columns]
    out = epl_pd[numeric].describe().round(1) if numeric else epl_pd.head()
else:
    _epl_pd = safe(
        'EPL standings (pandas)',
        lambda: parse_soccer_standings(
            soccer.espn_soccer_standings(league='eng.1', season=2023),
            return_as_pandas=True,
        ),
    )
    if _epl_pd is not None and not getattr(_epl_pd, 'empty', True):
        out = _epl_pd
    else:
        out = 'standings unavailable right now'
out
✅ EPL standings (pandas)


'standings unavailable right now'
🏅 Champions League deep-dive
A quick tour of the same surface on the UCL — demonstrating that the exact same parser stack handles group-stage multi-table standings.
ucl_board = safe(
    'UCL scoreboard',
    lambda: parse_soccer_scoreboard(
        soccer.espn_soccer_scoreboard(league='uefa.champions', dates=20231107)
    ),
)
if ucl_board is not None and getattr(ucl_board, 'height', 0):
    keep = [c for c in ucl_board.columns
            if c in ('short_name', 'home_score', 'away_score',
                     'status_type_description', 'date')]
    out = ucl_board.select(keep).head()
else:
    out = 'UCL scoreboard unavailable'
out
✅ UCL scoreboard


'UCL scoreboard unavailable'
# UCL group-stage standings — one row per team per group
if ucl_table is not None and getattr(ucl_table, 'height', 0):
    keep = [c for c in ucl_table.columns
            if c in ('group', 'rank', 'team_name', 'wins', 'draws', 'losses', 'points')]
    # Show Group A only
    if 'group' in ucl_table.columns:
        first_group = ucl_table['group'].sort()[0]
        out = (
            ucl_table
            .filter(pl.col('group') == first_group)
            .select(keep)
            .sort('rank')
        )
    else:
        out = ucl_table.select(keep).head(8)
else:
    out = 'run the UCL standings cell above first'
out
'run the UCL standings cell above first'
🌸 Women's soccer — NWSL & Women's World Cup
The same wrappers cover women's football. Swap the league slug:
usa.nwsl— National Women's Soccer League (NWSL)fifa.wwc— FIFA Women's World Cupeng.wsl— FA Women's Super Leagueusa.ncaa.w.soccer— NCAA Women's Division I
The nwsl sub-module alias mirrors the pattern of epl, mls, etc.
from sportsdataverse.soccer import nwsl

nwsl_table = safe(
    'NWSL standings 2023',
    lambda: parse_soccer_standings(
        nwsl.espn_nwsl_standings(season=2023)
    ),
)
if nwsl_table is not None and getattr(nwsl_table, 'height', 0):
    keep = [c for c in nwsl_table.columns
            if c in ('rank', 'team_name', 'wins', 'losses', 'draws', 'points', 'group')]
    out = nwsl_table.select(keep).head(10)
else:
    out = 'NWSL standings unavailable right now'
out
✅ NWSL standings 2023


'NWSL standings unavailable right now'
# Women's World Cup 2023 — group-stage standings
from sportsdataverse.soccer import wwc

wwc_table = safe(
    "WWC 2023 standings",
    lambda: parse_soccer_standings(
        wwc.espn_wwc_standings(season=2023)
    ),
)
if wwc_table is not None and getattr(wwc_table, 'height', 0):
    keep = [c for c in wwc_table.columns
            if c in ('group', 'rank', 'team_name', 'wins', 'draws', 'losses', 'points')]
    print('WWC groups:', wwc_table['group'].unique().sort().to_list() if 'group' in wwc_table.columns else 'n/a')
    out = wwc_table.select(keep).head(8)
else:
    out = 'WWC standings unavailable right now'
out
✅ WWC 2023 standings


'WWC standings unavailable right now'
📦 Event data from any provider with kloppy
ESPN gives you the match log; for per-event coordinates (every pass, carry, shot) the open standard is kloppy, which reads ~15 providers (StatsBomb, Opta, Wyscout, Sportec, SkillCorner, …) into one event model. It is an optional extra:
pip install "sportsdataverse[soccer]"
soccer_open_events('statsbomb', match_id) loads one match of
StatsBomb open data (free for research and
non-commercial use) as a polars frame — one row per event, snake_case columns, coordinates on
kloppy's 0–1 pitch by default (coordinates='statsbomb' keeps the 120 × 80 units).
Match 8658 is the 2018 World Cup final, France v Croatia.
from sportsdataverse.soccer import soccer_open_events

events = safe(
    'StatsBomb open data — 2018 World Cup final (match 8658)',
    lambda: soccer_open_events('statsbomb', 8658),
)
if events is not None:
    print('events:', events.shape)
    out = (
        events.filter(pl.col('event_type') == 'SHOT')
        .select('period_id', 'timestamp', 'team_id', 'player_id',
                'coordinates_x', 'coordinates_y', 'result')
        .head(10)
    )
else:
    out = 'kloppy not installed (pip install "sportsdataverse[soccer]") or StatsBomb open data unavailable'
out
✅ StatsBomb open data — 2018 World Cup final (match 8658)
events: (3036, 24)


shape: (10, 7)
┌───────────┬───────────────┬─────────┬───────────┬───────────────┬───────────────┬────────────┐
│ period_id ┆ timestamp     ┆ team_id ┆ player_id ┆ coordinates_x ┆ coordinates_y ┆ result     │
│ ---       ┆ ---           ┆ ---     ┆ ---       ┆ ---           ┆ ---           ┆ ---        │
│ i64       ┆ duration[μs]  ┆ str     ┆ str       ┆ f64           ┆ f64           ┆ str        │
╞═══════════╪═══════════════╪═════════╪═══════════╪═══════════════╪═══════════════╪════════════╡
│ 1         ┆ 17m 56s 987ms ┆ 785     ┆ 5472      ┆ 7.5           ┆ 41.5          ┆ OWN_GOAL   │
│ 1         ┆ 20m 51s 227ms ┆ 785     ┆ 5468      ┆ 111.5         ┆ 48.5          ┆ OFF_TARGET │
│ 1         ┆ 23m 34s 907ms ┆ 785     ┆ 5470      ┆ 107.5         ┆ 28.5          ┆ OFF_TARGET │
│ 1         ┆ 27m 53s 880ms ┆ 785     ┆ 5474      ┆ 104.5         ┆ 31.5          ┆ GOAL       │
│ 1         ┆ 37m 56s 787ms ┆ 771     ┆ 5487      ┆ 107.5         ┆ 39.5          ┆ GOAL       │
│ 1         ┆ 39m 25s 267ms ┆ 785     ┆ 5465      ┆ 107.5         ┆ 40.5          ┆ OFF_TARGET │
│ 1         ┆ 42m 47s 27ms  ┆ 785     ┆ 5474      ┆ 116.5         ┆ 33.5          ┆ BLOCKED    │
│ 1         ┆ 42m 50s 27ms  ┆ 785     ┆ 3471      ┆ 112.5         ┆ 25.5          ┆ BLOCKED    │
│ 1         ┆ 45m 17s 307ms ┆ 785     ┆ 5468      ┆ 114.5         ┆ 39.5          ┆ OFF_TARGET │
│ 2         ┆ 1m 10s 27ms   ┆ 771     ┆ 5487      ┆ 94.5          ┆ 44.5          ┆ SAVED      │
└───────────┴───────────────┴─────────┴───────────┴───────────────┴───────────────┴────────────┘
Any other provider or file goes through kloppy itself, then
soccer_events_to_frame(dataset) applies the same frame convention:
from kloppy import statsbomb
from sportsdataverse.soccer import soccer_events_to_frame
ds = statsbomb.load(event_data='8658.json', lineup_data='lineups_8658.json')
df = soccer_events_to_frame(ds)
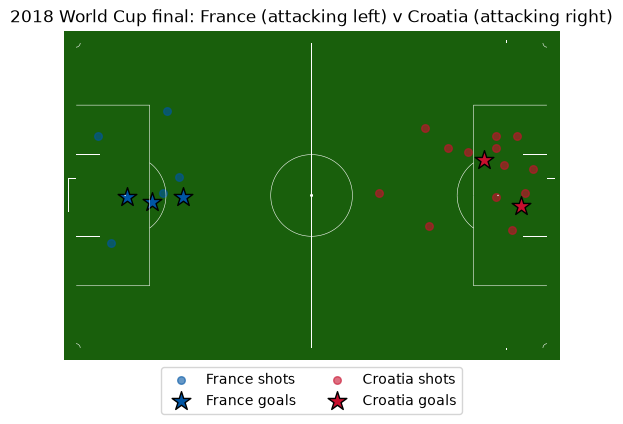
🎯 Chart: the final's shots on the pitch
sdvplot's pitch_coords puts StatsBomb's 120 × 80 units on the
105 × 68 m pitch surface("soccer") draws (the R twin is sdvplotR::sdv_pitch_coords). StatsBomb records every
shot as if the team attacked left to right, so flip= turns France's shots to the other end. The own goal is
dropped: it is recorded from the defending side.
# Needs the plotting extra: pip install --pre "sportsdataverse[soccer,sdvplot,sportypy]"
from IPython.display import Markdown, display

try:
    import matplotlib.pyplot as plt
    import sdvplot
    import sportypy  # noqa: F401 -- sdvplot.surface() draws with it
except ImportError:
    plt = None

shots = None if plt is None else safe('StatsBomb shots in StatsBomb units',
                                     lambda: soccer_open_events('statsbomb', 8658, coordinates='statsbomb'))
if plt is None or shots is None:
    display(Markdown('_Shot map skipped: it needs `pip install --pre "sportsdataverse[soccer,sdvplot,sportypy]"`._'))
else:
    TEAMS = {'771': ('France', '#0055a4'), '785': ('Croatia', '#c8102e')}  # StatsBomb team ids of match 8658
    shots = (shots.filter((pl.col('event_type') == 'SHOT') & (pl.col('result') != 'OWN_GOAL'))
             .with_columns(france=pl.col('team_id') == '771'))
    xy = sdvplot.pitch_coords(shots, provider='statsbomb', x='coordinates_x', y='coordinates_y', flip='france')

    ax = sdvplot.surface('soccer')
    for team_id, (team, color) in TEAMS.items():
        own = xy.filter(pl.col('team_id') == team_id)
        goals = own.filter(pl.col('result') == 'GOAL')
        ax.scatter(own['pitch_x'], own['pitch_y'], s=30, color=color, alpha=0.6, zorder=10, label=f'{team} shots')
        ax.scatter(goals['pitch_x'], goals['pitch_y'], s=200, marker='*', color=color, edgecolor='black', zorder=10, label=f'{team} goals')
    ax.set_title('2018 World Cup final: France (attacking left) v Croatia (attacking right)')
    ax.legend(loc='upper center', ncol=2, bbox_to_anchor=(0.5, 0))
    plt.show()
✅ StatsBomb shots in StatsBomb units
🧭 SPADL actions
soccer_spadl(dataset) converts any kloppy event dataset into
SPADL (Soccer Player Action Description Language): one
row per on-the-ball action, with every action oriented to attack left to right on a 105 × 68
pitch. soccer_open_dataset(...) is the dataset-returning twin of soccer_open_events(...).
from sportsdataverse.soccer import soccer_open_dataset, soccer_spadl

ds = safe('statsbomb open dataset 8658', lambda: soccer_open_dataset('statsbomb', 8658))
actions = safe('SPADL actions', lambda: soccer_spadl(ds)) if ds is not None else None
actions.head() if actions is not None else 'kloppy not installed (pip install "sportsdataverse[soccer]")'
✅ statsbomb open dataset 8658
✅ SPADL actions


shape: (5, 17)
┌─────────┬─────────────┬───────────┬───────────┬───┬─────────┬───────────┬───────────┬────────────┐
│ game_id ┆ original_ev ┆ action_id ┆ period_id ┆ … ┆ type_id ┆ type_name ┆ result_id ┆ result_nam │
│ ---     ┆ ent_id      ┆ ---       ┆ ---       ┆   ┆ ---     ┆ ---       ┆ ---       ┆ e          │
│ str     ┆ ---         ┆ i64       ┆ i64       ┆   ┆ i64     ┆ str       ┆ i64       ┆ ---        │
│         ┆ str         ┆           ┆           ┆   ┆         ┆           ┆           ┆ str        │
╞═════════╪═════════════╪═══════════╪═══════════╪═══╪═════════╪═══════════╪═══════════╪════════════╡
│ 8658    ┆ 6d7450f7-25 ┆ 0         ┆ 1         ┆ … ┆ 0       ┆ pass      ┆ 1         ┆ success    │
│         ┆ 90-4b04-a2a ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│         ┆ e-9ed116…   ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│ 8658    ┆ 1eb01089-03 ┆ 1         ┆ 1         ┆ … ┆ 21      ┆ dribble   ┆ 1         ┆ success    │
│         ┆ b0-46ac-9c5 ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│         ┆ a-6deeca…   ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│ 8658    ┆ d304b712-3d ┆ 2         ┆ 1         ┆ … ┆ 0       ┆ pass      ┆ 1         ┆ success    │
│         ┆ 28-4117-aea ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│         ┆ f-11c15a…   ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│ 8658    ┆ 99ef3a69-f4 ┆ 3         ┆ 1         ┆ … ┆ 21      ┆ dribble   ┆ 1         ┆ success    │
│         ┆ 06-45e7-b32 ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│         ┆ a-2f2f00…   ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│ 8658    ┆ a29c5a6c-6b ┆ 4         ┆ 1         ┆ … ┆ 0       ┆ pass      ┆ 1         ┆ success    │
│         ┆ 85-409e-a43 ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
│         ┆ b-03f2d6…   ┆           ┆           ┆   ┆         ┆           ┆           ┆            │
└─────────┴─────────────┴───────────┴───────────┴───┴─────────┴───────────┴───────────┴────────────┘
Valuing actions with Expected Threat
soccer_xthreat_rate(actions) appends an xt_value column: the change in
Expected Threat from each successful move
(pass, dribble, cross), using a grid bundled with the package and fit on StatsBomb open data.
SPADL coordinates are already 105 × 68 (origin bottom-left), so pass the start_x/start_y columns straight to a 105 × 68 pitch -- sdvplot's pitch_coords needs no provider conversion.
from sportsdataverse.soccer import soccer_xthreat_rate

rated = safe('xT values', lambda: soccer_xthreat_rate(actions)) if actions is not None else None
rated.head() if rated is not None else 'kloppy not installed (pip install "sportsdataverse[soccer]")'
✅ xT values


shape: (5, 18)
┌─────────┬────────────┬───────────┬───────────┬───┬───────────┬───────────┬───────────┬───────────┐
│ game_id ┆ original_e ┆ action_id ┆ period_id ┆ … ┆ type_name ┆ result_id ┆ result_na ┆ xt_value  │
│ ---     ┆ vent_id    ┆ ---       ┆ ---       ┆   ┆ ---       ┆ ---       ┆ me        ┆ ---       │
│ str     ┆ ---        ┆ i64       ┆ i64       ┆   ┆ str       ┆ i64       ┆ ---       ┆ f64       │
│         ┆ str        ┆           ┆           ┆   ┆           ┆           ┆ str       ┆           │
╞═════════╪════════════╪═══════════╪═══════════╪═══╪═══════════╪═══════════╪═══════════╪═══════════╡
│ 8658    ┆ 6d7450f7-2 ┆ 0         ┆ 1         ┆ … ┆ pass      ┆ 1         ┆ success   ┆ -0.002215 │
│         ┆ 590-4b04-a ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ 2ae-9ed116 ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ …          ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│ 8658    ┆ 1eb01089-0 ┆ 1         ┆ 1         ┆ … ┆ dribble   ┆ 1         ┆ success   ┆ 0.0       │
│         ┆ 3b0-46ac-9 ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ c5a-6deeca ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ …          ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│ 8658    ┆ d304b712-3 ┆ 2         ┆ 1         ┆ … ┆ pass      ┆ 1         ┆ success   ┆ -0.001096 │
│         ┆ d28-4117-a ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ eaf-11c15a ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ …          ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│ 8658    ┆ 99ef3a69-f ┆ 3         ┆ 1         ┆ … ┆ dribble   ┆ 1         ┆ success   ┆ -0.000256 │
│         ┆ 406-45e7-b ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ 32a-2f2f00 ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ …          ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│ 8658    ┆ a29c5a6c-6 ┆ 4         ┆ 1         ┆ … ┆ pass      ┆ 1         ┆ success   ┆ -0.001593 │
│         ┆ b85-409e-a ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ 43b-03f2d6 ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
│         ┆ …          ┆           ┆           ┆   ┆           ┆           ┆           ┆           │
└─────────┴────────────┴───────────┴───────────┴───┴───────────┴───────────┴───────────┴───────────┘
🎉 Where to next
- 📡 Full function list — every
espn_soccer_*wrapper is documented in the Soccer → Reference section of the sidebar. - 🔗 League aliases —
from sportsdataverse.soccer import epl, mls, ucl, laliga, bundesliga, seriea, ligue1, uel, nwsl, ligamx, wc, wwc— each pre-binds theleague=slug so your code reads cleaner. - 🐼 Pass
return_as_pandas=Trueto any parser, or call.to_pandas()on the polars frame — your favourite pandas / scikit-learn tooling works as-is. - ⚙️ For the raw ESPN payload (nested dict), call the wrapper without
parse_soccer_*wrapping. - 🌐 R user? The closest companion for European football data is worldfootballR. For ESPN basketball on the same platform, see wehoop (WNBA/WBB) and hoopR (NBA/MBB).
- Part of the SportsDataverse ecosystem.
Now go find the next gol de placa — the data's all here. ⚽🌟